Employer challenge
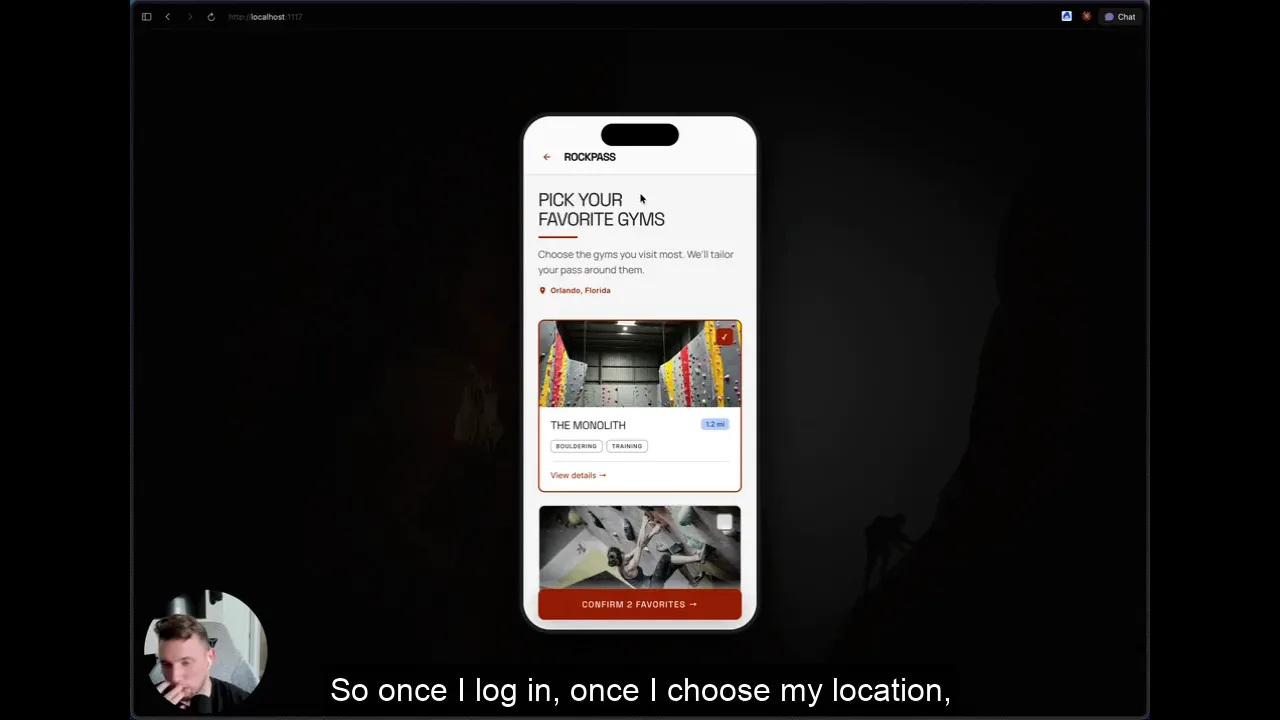
Pick an activity you're passionate about. Design a mobile app for people who share that passion. 60 minutes.
0:36
A technical program manager used to run the process; now they design the system that runs it. They decide which steps a model handles, which steps a person handles, and what happens when the model is wrong at 2am with nobody watching. Take the Proving Ground challenges to build a portfolio employers can see: scored work, plus a video walkthrough of how you think.
Employer challenge
Pick an activity you're passionate about. Design a mobile app for people who share that passion. 60 minutes.
Four challenges, each building on the last. Every one you complete is added to your Provn portfolio.
20 min
30 min
40 min
40 min
Four challenges, one company. Merrow Field Services is a mid-market commercial HVAC and refrigeration service company automating its dispatch, quoting and invoicing operation step by step. Do all four and your Profile shows one operation redesigned from the first step that should not have been automated to the product-wide rule for what stays human.
The competition is closed. The challenges aren’t. Every challenge you complete is scored and added to your Provn portfolio, where employers see your work.
Start the ladderWe sum the scores from your best approved attempt on each wave's challenge in this career ladder. Your best approved scores add up to 300. Practice does not count.
Up to two attempts per scored challenge; your best approved attempt counts. Unattempted challenges count as zero.
Standings change when an updated leaderboard is published. Equal scores share a rank.
At close, the Top 10 eligible entrants, including cutoff ties, advanced to judging. Judges select prize winners separately.
A ladder prize is not awarded if fewer than ten eligible entrants submit at least one scored challenge. Linked submission progress includes practice; it is not an approved-score or eligibility check.
Who judges this ladder
Dr. Jeremy Welland
Chief AI & Data Officer, Measure Well
Erin Rifkin
Founder, Mountain High Consulting
Naria Santa Lucia
General Manager, Microsoft Elevate, Microsoft
Synthesized from eleven live postings at Anthropic, OpenAI (two), Google DeepMind, Microsoft AI, NVIDIA, Amazon, Meta, Salesforce, Scale AI, and Anduril, read from employer careers boards on August 9, 2026. Not any one company's job description; the center of mass.
You are still the person who makes the program ship on time; now you are also the person who decides which of its steps a model is allowed to run unsupervised. The plan is yours, but so is the automation boundary, the control plan for when the model is wrong, and the adoption that decides whether any of it mattered.
| Ownership area | What it means |
|---|---|
| You own delivery of a cross-functional program in which some steps are now automated by a model | The plan is still yours. What is new is the design underneath it: which steps run automatically, which stay human, what routes between them, and what happens on failure. |
| You own end-to-end execution of a cross-functional program | scope, sequence, dependencies, milestones, risk register, and the operating rhythm that keeps it visible. Named in every posting. |
| You own the automation boundary | Which steps run automatically, which stay human, which are human-reviewed, and the confidence or exception rule that routes between them. This decision did not exist in this job five years ago. |
| You own launch readiness | The criteria a model-backed workflow must meet before production, the review that gates it, and the go/no-go call. At the labs this is formal: pre-launch safety reviews, setting safety bars, launch readiness reviews. |
| You own the control plan for wrong output | Detection, containment, fallback, rollback trigger, owner, and the record of what the system did and why. You are accountable for the cost of an automated mistake, not just the schedule. |
| You own adoption | The program is done when the people who were supposed to change their work have changed their work. Anduril: “through launch and adoption.” |
| You own capacity and unit economics of the operation | headcount, staffing forecasts, FTE budget, compute quota, cost per transaction. Scale AI, Google and NVIDIA all put a budget or capacity line in the TPM's scope. |
| You own the executive narrative | Program status, risk and trade-offs, written for people who will not read the tracker. Amazon makes the narrative itself the substance of the job. |
You work with engineering and platform teams as the primary counterpart; with ML researchers and data scientists as first-class partners at the labs (Anthropic requires depth sufficient for meaningful engagement with researchers; Google's TPM designs and integrates evaluations); with the operating teams whose work the system changes, who decide whether adoption happens; and with legal, security, privacy and safety reviewers as gates you route through. Five or more years of TPM or product-operations experience is the norm; the range runs from 3+ at Salesforce. Six of eleven name or prefer a degree.
The job title says AI Operations. The job description describes a 2019 TPM. A challenge tells you which one the candidate actually is.
Four of eleven postings put any AI requirement in the required bar. Salesforce titles the job AI Operations Technical Program Manager and requires PaaS and agile.
Ten shifts show up across the postings. The first two are the reason the fourth challenge is called What Stays Human.
| Shift | What changed |
|---|---|
| The operator designs the system instead of running the process | The pre-AI artifact was a plan: who does what by when. The AI-era artifact is a design: which steps are automated, which are human, what routes between them, what happens on failure. |
| “What stays human” became a real decision with a real cost on both sides | Automate too much and you eat error cost you did not model. Automate too little and you miss the savings the program was funded on. Everyone draws this line in 2026; almost no JD says how. |
| Risk changed category | It used to be schedule risk. Now it is output risk: will the automated step be wrong, how often, how expensively, and who finds out. OpenAI's Strategic Initiatives TPM does nothing else. |
| Launch readiness became program management's problem | Six of eleven postings put a gate on the TPM. For a probabilistic release someone has to decide what accuracy is good enough. |
| Adoption became an owned outcome rather than a rollout phase | If people quietly keep doing it the old way, the program failed even though it shipped. |
| The TPM is expected to build, not only coordinate | NVIDIA's requirement is unambiguous: build the agents, dashboards, scripts and automations yourself. “Built automations” on a resume is a claim; a walkthrough is evidence. |
| Capacity planning now means compute and annotation supply, not just people | Google's TPM manages compute capacity for an eval platform; Scale's monitors FTE budgets for a delivery workforce; Microsoft AI has a whole req for cluster operations and quota. |
| A new counterpart appeared: the researcher | A TPM who can only translate between PM and engineering is now one counterpart short. |
| Governance is a gate on the plan, not a compliance appendix | Documented mitigations, safety bars, auditability, security and privacy review consume schedule and cannot be launched around. |
| The transformation is deeply uneven, and the JDs cannot tell the candidates apart | Amazon asks for one year of partnering with AI/ML teams. Anthropic requires meaningful engagement with researchers. Same title. |
How often each skill appears across eleven postings. Note how few put AI in the required bar, and how many describe an AI program.
| Skill | Postings | Note |
|---|---|---|
| Cross-functional execution: scope, dependencies, risk, milestones | 11 / 11 | Unchanged from a pre-AI TPM |
| Communicate status, risk and trade-offs to executives | 11 / 11 | Amazon makes the narrative itself the deliverable |
| Bringing structure to ambiguity | 10 / 11 | not scored |
| Technical fluency sufficient to engage engineers or researchers | 9 / 11 | From “convey requirements” (Amazon) to “meaningful engagement with ML researchers” (Anthropic) |
| Build repeatable process: SOPs, playbooks, operating rhythms | 8 / 11 | Anthropic, Microsoft, OpenAI, Anduril name the artifact |
| Define and track metrics, KPIs, quality indicators, SLAs | 7 / 11 | not scored |
| Influence without authority | 7 / 11 | not scored |
| Launch readiness / release gating for a model-backed system | 6 / 11 | Anthropic, OpenAI ×2, Google, Anduril, Amazon |
| Risk assessment, safety bars, governance, compliance review | 5 / 11 | OpenAI's Strategic Initiatives req is almost entirely this |
| Capacity, forecasting, headcount, or budget ownership | 4 / 11 | Scale, Google, NVIDIA, Amazon |
| Own adoption of the new workflow, not just its delivery | 4 / 11 | Anduril, NVIDIA |
| Reduce manual effort through automation, as an owned outcome | 4 / 11 | Meta, NVIDIA, Anduril, OpenAI |
| Model evaluations, eval infrastructure, loss analysis | 3 / 11 | Google, OpenAI, Anthropic |
| Personally build agents, scripts, dashboards, automations | 2 / 11 | NVIDIA (hard requirement), Anduril |
Four of eleven postings have any AI requirement in the required bar, and seven describe a program with automated steps. Agile and SDLC methodology is named in three. No posting names a program-management tool.
So no rubric here awards points for a methodology or a tool. We score the design: did you find the step that needs a human back in it and say why in numbers; did you sequence the rollout against real constraints and name what you cut; did you recover the program without more people; did you price the errors on both sides of the automation line.
Two tiers, split differently from the PM hub. Tier 1 (Anthropic, OpenAI, Google DeepMind, NVIDIA) hire an operator who works inside the AI system: launch readiness for models, eval infrastructure, compute capacity, safety bars, and at NVIDIA building the automation. Tier 2 (Salesforce, Meta, Amazon, Anduril) hire a conventional cross-functional TPM and point them at an AI program. Microsoft AI and Scale AI sit between.
Anthropic
$365K to $435K
TPM, Launches: launch readiness for models; requires technical depth for meaningful engagement with ML researchers.
Tier 1
OpenAI
$257K to $445K + equity
Strategic Initiatives TPM tracks a stack of existing and future mitigations for every major product and model risk; Applied API & Product TPM owns launch execution.
Tier 1
Google DeepMind
$217K to $237K + bonus + equity
TPM, Gemini Evals: designs and integrates model evaluations with data scientists, conducts loss analysis, manages compute capacity for the eval platform.
Tier 1
NVIDIA
$168K to $258.8K
AI-Native TPM: build the agents, dashboards, scripts and workflow automations yourself. The single biggest departure from the traditional job.
Tier 1
Microsoft AI
$119.8K to $258K
Senior TPM, Copilot AI; a separate req for cluster operations and quota management; SOPs and operating rhythms named.
Amazon
$148.7K to $201.2K
Sr. TPM, Applied AI Solutions Finance: translating technical initiatives into executive narratives is the substance of the job; one year of partnering with AI/ML teams.
Tier 2
Meta
$167K to $230K + bonus + equity
TPM, AI Infrastructure; reduce manual effort through automation as an owned outcome; agile named.
Tier 2
Scale AI
$151.2K to $189K
TPM, Gen AI Operations Planning: monitors account-level FTE budgets for a human delivery workforce; nine TPM reqs live.
Salesforce
$123.1K to $186.3K
AI Operations TPM, Heroku: the title says AI Operations; the requirements say PaaS and agile.
Tier 2
Anduril
$129K to $171K
TPM, AI Platform: “from opportunity framing through launch and adoption”; agentic workflows named; implementation support expected.
Tier 2
Provn is not affiliated with any employer listed. Descriptions summarize each company's public job posting as read in August 2026.
Every tier is scored on the same five dimensions. Strategic judgment and sequencing carries 20 on Challenge 2 and Challenge 3, because rollout and recovery are sequencing problems; core execution rises to 35 on Challenge 4, because the automation-boundary design is the deliverable.
Advance at 75. Draft Board at 80.
| Dimension | Challenge 1 | Challenge 2 | Challenge 3 | Challenge 4 |
|---|---|---|---|---|
| Core execution / operational judgment | 40 | 30 | 30 | 35 |
| AI-first operations design | 25 | 20 | 20 | 20 |
| Strategic judgment / sequencing | not scored | 20 | 20 | 15 |
| Video walkthrough & communication | 20 | 20 | 20 | 20 |
| AI fluency | 15 | 10 | 10 | 10 |
On The Step That Shouldn't Be Automated, Transformative names the step, shows the error-cost arithmetic that makes it the right one (not the step with the highest error rate, the one with the highest cost per error times volume), specifies the control (trigger, threshold, owner), and says what the human in the loop costs per week. Adoptive names the right step with a cost argument and a control; that is the advance bar. Capable picks the step with the worst error rate. Below Capable picks a plausible step but with no cost argument to justify it. Not Yet proposes turning the automation off.
Communication is judged on whether the person you are explaining to could act on your video alone. Never on accent, pace, or filler words.
Questions derived from what the postings actually ask for, each with the shape of a strong answer. The ladder produces evidence for every one of them.
Cost per error times volume, not error rate. The strong answer specifies the control (what triggers review, what threshold, who owns it) and the weekly cost of the human, and says what it would need to see to remove them again.
Where it comes from: Robinhood and Anduril name where human judgment stays in the loop; four of eleven name reducing manual effort as an owned outcome.
Depends on what the 6% cost and who catches them. State the readiness criteria per failure class, the review that gates it, and the rollback trigger. The strong answer names what it would ship at 94% with review and what needs 99%.
Where it comes from: Six of eleven postings put a launch gate on the TPM; Anthropic and OpenAI make it formal.
Find the dependency that is actually late, not the team that is loudest. Re-sequence so the critical path shortens, cut scope with the cost named, and write the executive narrative before you are asked for it.
Where it comes from: Eleven of eleven name cross-functional execution and executive communication; Amazon makes the narrative the deliverable.
Yours. Adoption is the outcome. The strong answer diagnoses why (the automated step failed in a way the frontline did not trust, or the workaround was faster) and proposes the fix and the metric that shows people actually changed their work.
Where it comes from: Anduril: through launch and adoption. MIT NANDA, August 2025: most enterprise AI pilots show no measurable P&L impact.
A script, a dashboard, an agent, a workflow integration, with what it replaced and where it failed. This is also the shape of the mandatory AI question in your video.
Where it comes from: NVIDIA requires it outright; Anduril and OpenAI ask indirectly.
Yes, and the top of the market moved sharply: Anthropic posts $365K to $435K for a Launches TPM and OpenAI $257K to $445K. The job changed from running a process to designing the system that runs it, and most postings have not caught up, which means most screens cannot see the difference. The ladder can.
Nine of eleven require technical fluency sufficient to engage engineers; four require enough to engage ML researchers. Six name or prefer a degree; none of the challenges requires code. What they require is that you can say what “working” means numerically and design the control when it does not.
The automation boundary, output risk, launch gating for probabilistic systems, and adoption as an owned outcome. The first challenge is the smallest version of the new job: one workflow, one step that needs a human back in it, and the arithmetic that proves it.
About two hours ten minutes: 20, 28, 40 and 40 minutes including video. All four share the Merrow scenario.
Three of eleven name agile; none names a tool. We score the design and the sequencing, not the vocabulary.
The Draft Board is the group of builders whose challenge work scores 80 or above. Employers hiring on Provn start there. Any tier of this ladder can put you on it.
Yes, and we score how. Every challenge asks for an AI usage log and a mandatory video moment where you name a place you redirected the AI.
Start with the first 20-minute challenge today. Read the whole challenge first; sign up when you are ready to submit.