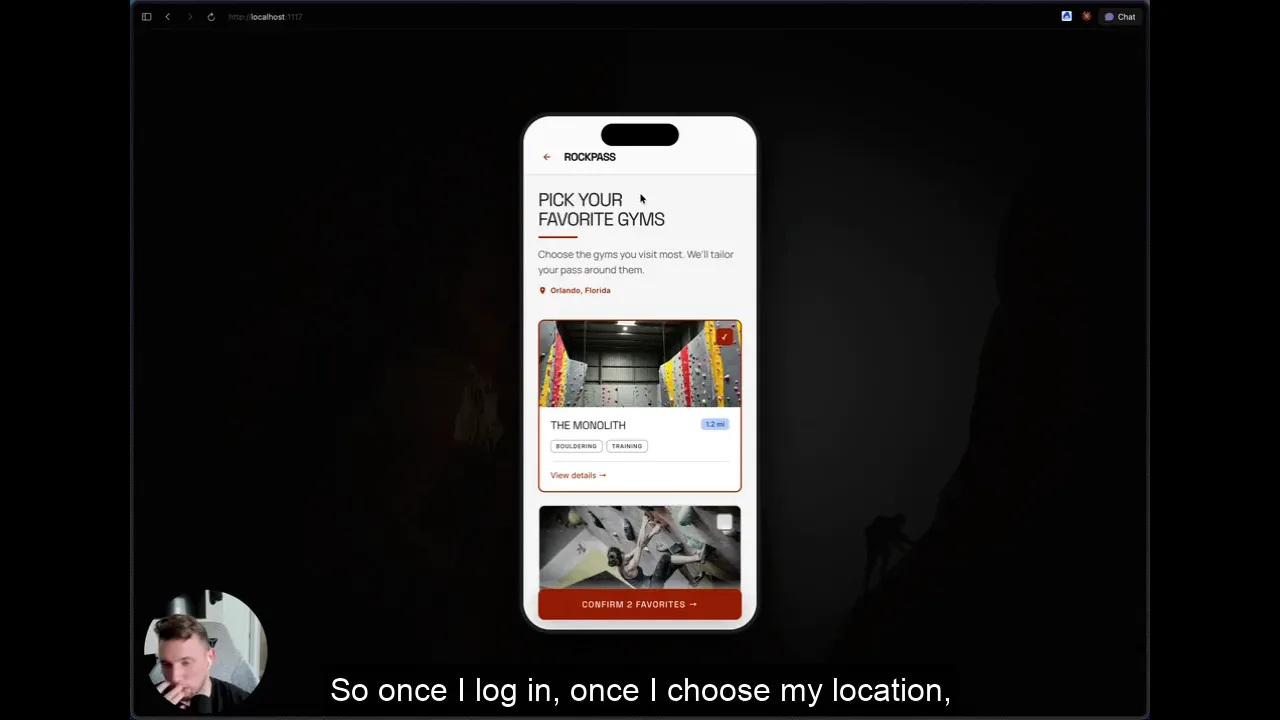
Employer challenge
Pick an activity you're passionate about. Design a mobile app for people who share that passion. 60 minutes.
0:36
A data analyst turns ambiguous business questions into answers a decision-maker can act on. What changed is that a model can now write the query, run it, and narrate a plausible, confident, wrong result. The job moved from producing the number to trusting it. Take the Proving Ground challenges to build a portfolio employers can see: scored work, plus a video walkthrough of how you think.
Employer challenge
Pick an activity you're passionate about. Design a mobile app for people who share that passion. 60 minutes.
Four challenges, each building on the last. Every one you complete is added to your Provn portfolio.
20 min
30 min
40 min
40 min
Four challenges, one business. Marlowe Athletic is a mid-market fitness chain: 84 clubs across the Southeast and Midwest, roughly 310,000 members, three tiers (Base $29, Plus $49, Peak $79), a booking app, and a data team of four. Do all four and your Profile accumulates domain knowledge the way a real analyst's does. No tier asks for a chart.
The competition is closed. The challenges aren’t. Every challenge you complete is scored and added to your Provn portfolio, where employers see your work.
Start the ladderWe sum the scores from your best approved attempt on each wave's challenge in this career ladder. Your best approved scores add up to 300. Practice does not count.
Up to two attempts per scored challenge; your best approved attempt counts. Unattempted challenges count as zero.
Standings change when an updated leaderboard is published. Equal scores share a rank.
At close, the Top 10 eligible entrants, including cutoff ties, advanced to judging. Judges select prize winners separately.
A ladder prize is not awarded if fewer than ten eligible entrants submit at least one scored challenge. Linked submission progress includes practice; it is not an approved-score or eligibility check.
Who judges this ladder
Dr. Jeremy Welland
Chief AI & Data Officer, Measure Well
Kacy Harding
Chief Product Officer, Advanced Analytics, ING
Synthesized from ten live postings at Anthropic, Netflix, Reddit, Stripe, Databricks, Capital One, Amazon, Meta, Instacart, and McKinsey/QuantumBlack, read from employer careers boards on August 9, 2026. Not any one company's job description; the center of mass.
You are no longer the only thing in the company producing an answer. A model can write the query, run it, and narrate the result in fluent English. You own whether that answer is right.
| Ownership area | What it means |
|---|---|
| You own the question, before the query | Translating an open business question into an analytical approach, choosing the method, and stating what the analysis can and cannot establish. Named in all ten postings. |
| You own correctness | Of your own work, and of analysis produced by AI tools, self-serve assistants, and stakeholders who now generate their own numbers. You own the claim, whoever typed it. |
| You own metric definition | What churn, active, retention or quality means in this company, what the denominator is, and when a metric has stopped measuring what it was built to measure. |
| You own experimental and causal reasoning | Experiment design where an experiment is possible, and honest quasi-experimental reasoning where it is not, which is most of the time. |
| You own evaluation of model-produced output | Where the product is AI-powered, you define how quality is measured: the gold set, the pass criteria, the sampling, the regression bar. |
| You own the recommendation | The deliverable is a decision, not a dashboard. Employers say this in ten different ways and never once say “make good charts.” |
You work with product, engineering and business stakeholders as the person who tells them what is true, including when it is inconvenient; with executives in writing (nine of ten make communication to a non-technical audience explicit); with applied scientists where the company builds model-powered products; and increasingly with the AI tools themselves as a first-class working relationship. Experience runs from 2+ years at Amazon and McKinsey to 12+ at Reddit for the same core craft at different scale. SQL and Python at working depth are named in nine of ten; an advanced degree is preferred in five and required in none.
The highest-paying data science job descriptions in America cannot tell you whether the candidate can catch a wrong number produced by a model. A challenge can.
Five of ten postings (Netflix, Meta, Stripe, Databricks, Reddit) contain no AI language and sit at the top of the pay range.
Nine shifts show up across the postings and the industry benchmarks the pack cites. The first two are the whole story.
| Shift | What changed |
|---|---|
| The bottleneck moved from writing the query to trusting the answer | dbt Labs' April 2026 benchmark put text-to-SQL at 90% accuracy against a well-modeled schema. Producing SQL is close to solved. The remaining 10% is the entire job. |
| Wrong now looks right | Models subtly join tables incorrectly or misinterpret a column and “cheerfully give you a wrong answer.” Failure used to look like an error message. Now it looks like a plausible number. |
| Evaluating AI systems became a listed qualification | Amazon's Data Scientist, Sales AI carries one year of evaluating AI systems in its basic qualifications, not preferred. McKinsey asks candidates to assess LLM output quality. |
| The analyst became a reviewer of analyses they did not write | Self-serve now means a natural-language agent that answers any question anyone types. The population who can generate a wrong number went from the data team to the whole company. |
| Verification became a budgeted activity | If a model answers a thousand questions a month and 11% are confidently wrong, someone decides how many get checked, by whom, at what cost. That arithmetic now sits with the data function. |
| The chart stopped being the deliverable | Data visualization is named in two of ten postings. Influencing a decision through insight appears in eight. No tier of this ladder asks you to make a chart. |
| AI fluency arrived at the analyst tier before the scientist tier | Instacart's Senior Data Analyst posting names the AI assistants by brand and treats fluency as part of the job. The transformation is running bottom-up. |
| Domain knowledge got repriced upward | The skill that catches a wrong output is knowing a 3.2% churn rate is impossible for that business in that month. Generic technique does not catch it. A resume cannot show it. A challenge can. |
| Half the market has not changed its job description at all | Netflix, Meta, Stripe, Databricks and Reddit are hiring the same data scientist they hired in 2021 and hoping AI judgment arrives with them. |
How often each skill appears across ten postings. Note how far down the list AI evaluation sits, and how high the pay is at the employers that omit it.
| Skill | Postings | Note |
|---|---|---|
| Translate an ambiguous business question into an analytical approach | 10 / 10 | The one universal |
| Communicate to a non-technical / cross-functional audience | 10 / 10 | Databricks and Anthropic make it an explicit qualification |
| SQL, named explicitly | 9 / 10 | Netflix is the sole exception, and pays the most |
| Python (alone or with R / Scala) | 9 / 10 | Same exception |
| Influence a product or business decision through insight | 8 / 10 | The framing is always “drive,” never “report” |
| Machine learning or statistical modeling | 7 / 10 | not scored |
| Define metrics / build a measurement framework | 6 / 10 | not scored |
| Experimental design, causal inference, A/B testing | 5 / 10 | Named hardest at Reddit, Netflix, Anthropic, Amazon |
| Advanced degree preferred or required | 5 / 10 | Required in zero of the ten |
| Work with LLMs, RAG, prompting, or agentic workflows | 4 / 10 | Amazon, Capital One, McKinsey, Instacart |
| Build self-serve data products for non-analysts | 4 / 10 | The premise of the fourth challenge |
| Evaluate AI / LLM output quality as a named responsibility | 2 / 10 | Amazon, McKinsey |
| Data visualization, named as a skill | 2 / 10 | Anthropic, Databricks. That is all |
Two of ten postings name a chart. Eight name influencing a decision. So no tier of this ladder asks for a visualization, and no rubric awards points for one. We score whether you saw the mechanism behind the metric, separated a real effect from a selection effect, caught the correct query answering the wrong question, and committed to a number and a recommendation anyway.
Tools are named sparingly and generically across the sample: SQL, Python, warehouse and BI tooling. No posting screens on a specific BI product or notebook environment. We do not either.
Two tiers, and the split is not where you would expect. Tier 1 (Amazon, Capital One, McKinsey/QuantumBlack, Instacart, Anthropic) write AI directly into the data role: LLM evaluation, RAG pipelines, agentic workflows, benchmark design, or AI-assisted analysis as a named responsibility. Tier 2 (Netflix, Meta, Stripe, Databricks, Reddit) pay at or above Tier 1 and their postings contain no AI language at all.
Anthropic
$275K to $370K
Data Scientist, Safeguards: the same posted range on Developer Productivity. Communication to a non-technical audience is an explicit qualification.
Tier 1
Netflix
Range not shown on posting
L6 Member Product; the mirror shows $300K to $900K but the posting did not render. Hypothesis-driven analysis and experimentation named hardest; no SQL or Python named, and pays the most.
Tier 2
$268K to $365.1K
Principal Data Scientist, Ads, 12+ years; experimental design and causal inference at the top of the bar.
Tier 2
Stripe
$192K to $288K
Core Infrastructure data science; a classical 2021 posting at the top of the pay range.
Tier 2
Databricks
$192K to $260K
Staff Data Scientist; communication to cross-functional partners is an explicit qualification; visualization one of two postings to name it.
Tier 2
Amazon
$153.4K to $207.5K
Data Scientist, Sales AI: one year of working with or evaluating AI systems is a basic qualification; benchmark design for GenAI performance preferred. The only verifiable volume hirer.
Tier 1
Capital One
$176.5K to $201.4K
Principal Data Scientist, AI Foundations, Specialist Models: model work written into the analyst's job.
Tier 1
Meta
$147K to $208K + bonus + equity
Product Analytics; a classical posting with no AI language.
Tier 2
Instacart
$131K to $165.5K
Senior Data Analyst names the AI assistants by brand and treats fluency with them as part of the job. AI fluency arriving at the analyst tier first.
Tier 1
McKinsey / QuantumBlack
No range posted
Data Scientist I-II; asks candidates to assess LLM output quality and hallucination.
Tier 1
Provn is not affiliated with any employer listed. Descriptions summarize each company's public job posting as read in August 2026.
Every tier is scored on the same five dimensions. Analytical rigor is the core; the AI-specific dimension is scrutiny of model-produced analysis, which rises to 25 on Challenge 3 and Challenge 4 because that is where the agent's answers live.
Advance at 75. Draft Board at 80.
| Dimension | Challenge 1 | Challenge 2 | Challenge 3 | Challenge 4 |
|---|---|---|---|---|
| Analytical rigor (core execution) | 40 | 35 | 30 | 30 |
| AI-specific: scrutinizing model-produced analysis | 25 | 20 | 25 | 25 |
| Strategic judgment / insight-to-recommendation | not scored | 15 | 15 | 15 |
| Video walkthrough & communication | 20 | 20 | 20 | 20 |
| AI fluency | 15 | 10 | 10 | 10 |
On Grade the Agent's Answer, Transformative identifies that the query is syntactically and even logically correct but answers a different question than the executive asked (the denominator, the population, or the window is wrong), quantifies how far off the recommendation is, and rewrites it with the arithmetic shown. Adoptive finds the mismatch and corrects the recommendation; that is the advance bar. Capable checks the SQL, finds no bug, and endorses the answer with caveats. Below Capable senses something is off but cannot say what, and hedges without correcting the recommendation. Not Yet restates the agent's recommendation.
Communication is judged on whether the person you are explaining to could act on your video alone. Never on accent, pace, or filler words.
Questions derived from what the postings actually ask for, each with the shape of a strong answer. The ladder produces evidence for every one of them.
Not on that evidence. People who attend classes are already the members least likely to leave. The strong answer proposes how to separate the effect from the selection (a holdout, a matched cohort, a natural experiment in club openings) and still commits to a number and a recommendation the business can act on this quarter.
Where it comes from: Five of ten postings name experimental design and causal inference; Reddit, Netflix, Anthropic and Amazon name it hardest.
Read the question, then the query, then the number, in that order. Denominator, population, window, join logic. The strong answer says which failure is most likely for this schema and how long it took to find it, because that time is the verification budget.
Where it comes from: Amazon: evaluating AI systems as a basic qualification. McKinsey: assess LLM output quality. dbt Labs benchmark: failure looks like a plausible but incorrect answer.
Numerator, denominator, population, window, and the edge cases: freezes, tier downgrades, transfers between clubs, failed payments. The strong answer states what the metric is for and when it would stop measuring that.
Where it comes from: Six of ten postings name metric definition and measurement frameworks.
The ones with the highest cost of being wrong, not a random sample: anything that drives spend, headcount, or pricing, and anything where the query touched a table with known definitional traps. The strong answer states the sampling rule and what changes it.
Where it comes from: Verification as a budgeted activity; Capital One and Instacart write AI into the analyst's job.
Name the specific case, what made it implausible before you checked (domain knowledge, base rates, an impossible ratio), and what the verification found. Generic answers about “always validating” score poorly. This is also the shape of the mandatory AI question in your video.
Where it comes from: Domain knowledge as the skill that catches wrong output; ten of ten name translating an ambiguous question.
Yes, and the postings show why: producing the query is close to solved and the remaining work (deciding what to ask, catching plausible wrong answers, defining metrics, committing to a recommendation) is the job. Amazon alone has over a hundred open data reqs; posted ranges run from $131K to $370K.
Five of ten postings prefer one. Zero require it. What every posting requires is the ability to turn an ambiguous question into an analytical approach and communicate the answer to a non-technical audience. The ladder scores exactly that.
Because two of ten employers name visualization and eight name influencing a decision. We score the mechanism you found and the recommendation you made. You are welcome to include a chart in your deliverable; it earns no points on its own.
About two hours ten minutes: 20, 28, 40 and 40 minutes including video. All four share the Marlowe Athletic scenario.
No. Postings name SQL and Python at working depth and generic warehouse and BI tooling. No rubric here awards points for a product name.
The Draft Board is the group of builders whose challenge work scores 80 or above. Employers hiring on Provn start there. Any tier of this ladder can put you on it.
Yes, and we score how. The third and fourth challenges are about evaluating AI-produced analysis, so your own AI usage log is part of the evidence. Every video includes the mandatory moment where you name a place you redirected the AI.
Start with the first 20-minute challenge today. Read the whole challenge first; sign up when you are ready to submit.