Employer challenge
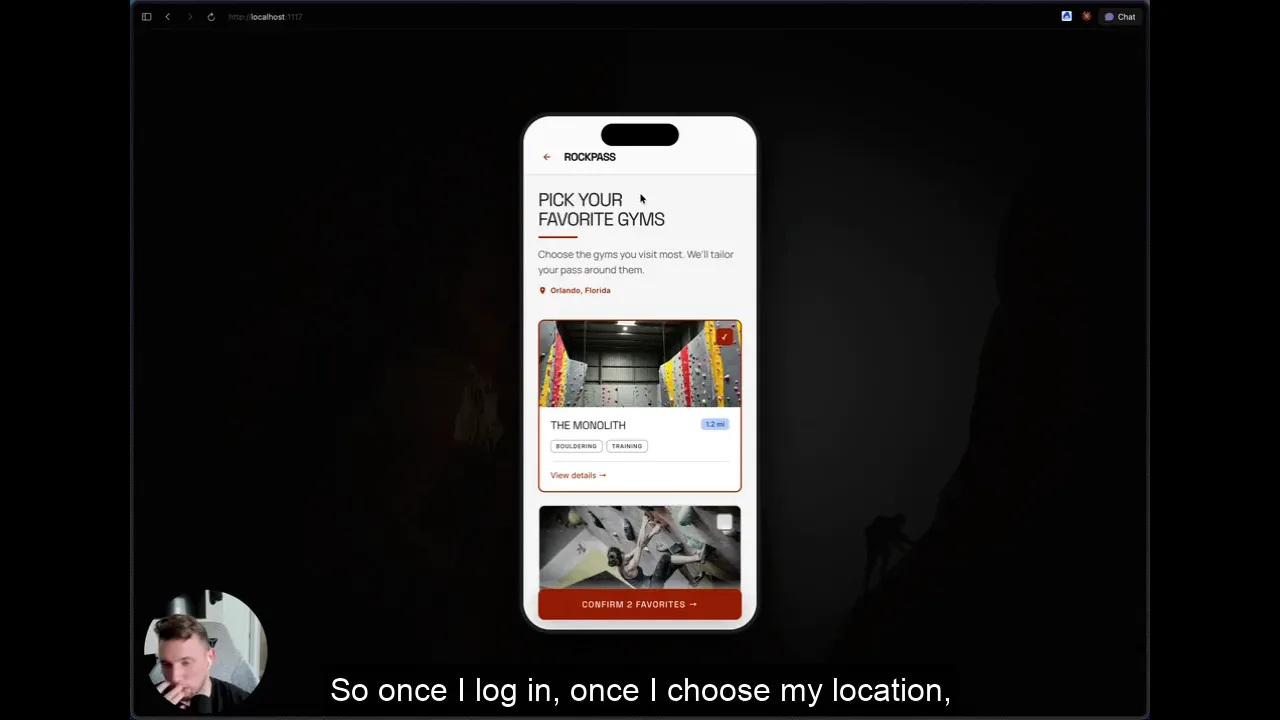
Pick an activity you're passionate about. Design a mobile app for people who share that passion. 60 minutes.
0:36
A forward-deployed engineer turns a customer's vague want for “an AI system” into something bounded, buildable, and measurable, then owns the number it produces inside the customer's own environment. The market now hires two versions of the job: one measured on the conversation, one on the code. Take the Proving Ground challenges to build a portfolio employers can see: scored work, plus a video walkthrough of how you think.
Employer challenge
Pick an activity you're passionate about. Design a mobile app for people who share that passion. 60 minutes.
Four challenges, each building on the last. Every one you complete is added to your Provn portfolio.
Scoping, expectation-setting, diagnosis, and architecture defense. No executable output is required at this ladder by design; the scarce skill here is judgment, and the video is a work sample, not a walkthrough.
20 min
30 min
40 min
40 min
Building inside Meridian's AWS account: the code, the integration, the eval on their data, the guardrail, the runbook. Complete the four challenges in order to build on your earlier work.
20 min
30 min
40 min
40 min
Two ladders, one customer. Meridian Freight Systems is a mid-market less-than-truckload freight brokerage: a fourteen-year-old TMS, EDI, carrier portals with no API, a spreadsheet one person maintains by hand, and a buyer who is genuinely non-technical. The customer-facing ladder scopes the engagement, sets the expectation, diagnoses the stall, and defends the architecture in the room. The full-stack ladder builds the thing inside Meridian's AWS account. Run both and your Profile shows one engagement from two angles.
The competition is closed. The challenges aren’t. Every challenge you complete is scored and added to your Provn portfolio, where employers see your work.
Start the ladderWe sum the scores from your best approved attempt on each wave's challenge in this career ladder. Your best approved scores add up to 300. Practice does not count.
Up to two attempts per scored challenge; your best approved attempt counts. Unattempted challenges count as zero.
Standings change when an updated leaderboard is published. Equal scores share a rank.
At close, the Top 10 eligible entrants, including cutoff ties, advanced to judging. Judges select prize winners separately.
A ladder prize is not awarded if fewer than ten eligible entrants submit at least one scored challenge. Linked submission progress includes practice; it is not an approved-score or eligibility check.
Who judges this ladder
Ranga Komanduri
Head of Engineering, OptiMantra
Ludo Hauduc
CEO & Co-founder, Empwr.ai
Bhavesh Mehta
Vice President of Engineering, CyberSecurity, Meta
Ganesh Baskaran
Chief Product & Technology Officer, arrivia
Jay Bartot
Chief Technology Officer, Lev
Rich Evans
Founder & CTO, AZX
Synthesized from twenty live postings across two packs, read August 9 to 10, 2026: a customer-facing set (OpenAI, Anthropic, Databricks, Google Cloud, AWS, NVIDIA, Salesforce, Vercel, Cresta, Glean) and a full-stack build set (OpenAI, Palantir, Anthropic, Google Cloud, AWS Professional Services, Scale AI, Databricks, Baseten, Vercel, Cognition). OpenAI, Anthropic, Google, AWS, Scale, Databricks and Vercel run both under different titles, and do not agree which one to pay more.
You are the person a customer talks to when they want an AI system and do not know what they want. On the customer-facing ladder you write code when it is the fastest way to make the point, but you are measured on whether the customer's problem got smaller. On the full-stack ladder you write production code inside the customer's cloud account, against systems you cannot change, on data you did not clean, under a security review you did not schedule.
| Ownership area | What it means |
|---|---|
| You own the scope | Discovery, decomposition, and a written statement of what you will deliver and by when. Named in nine of ten customer-facing postings. What you did not promise is what protects the engagement. |
| You own the expectation | You are selling a system that is right most of the time. Somebody has to tell the customer what “most” means, in a number, and what happens on the other days. If you do not do it in week one, you do it in week six, in a worse room. |
| You own the measurement | You define what “working” means in this customer's environment, because nobody at headquarters can see their traffic. If you do not build the eval, there is no eval. |
| You own the integration surface and the deployment | Connectors, ingest jobs, retries, backfills; customer VPCs, private endpoints, IAM permission boundaries, image scanning, change windows. Named at Scale, AWS, Vercel, OpenAI and Palantir. |
| You own the guardrail | When the system writes a record, sends a message, or quotes a price on the customer's behalf, you own the mechanism that stops it doing that wrongly, not the policy that says it should not. |
| You own the relationship, including the hostile parts | The executive sponsor whose budget this is. The IT or security owner who did not choose you and controls whether you ship. The frontline users whose willingness to use the thing is the real success metric. |
| You own operability after you leave | Runbooks, alarms, upgrade procedures, and the handover to a customer team that did not write any of it. Two of ten build postings mention runbooks; all ten describe a job where the customer owns the system afterward. |
You work with the customer's executive sponsor (non-technical, budget owner), their IT and security function, their frontline users, and, on the build ladder, their engineers in their repo and their code review. You work alongside your own account team; six of ten customer-facing postings pair you with a seller and Databricks asks for a quota track record outright. Experience floors run from 3+ years (Cresta) to 10 (Google Customer Engineer III). Travel of 25 to 50% is stated in six of ten. Python plus one of TypeScript, Go, Java or SQL is the floor.
Every one of these postings states its hiring bar as a disposition: high tolerance for ambiguity, self-directed by default, high customer empathy, trusted advisor. A resume cannot evidence trustworthiness. A scoping note and a five-minute video can.
Finding across the customer-facing pack; five of ten postings make “trusted advisor” a responsibility bullet.
The two ladders share a customer and split on where the hardest skill lives. Ten shifts show up across both packs and matter for both jobs.
| Shift | What changed |
|---|---|
| Expectation-setting became a technical skill with a number in it | “87%, and here is what happens the other 13% of the time, and here is who catches it.” Before 2023 this sentence had no place in a solutions architect's job. Now it is the first hard conversation of every engagement. |
| The customer's evaluation framework became a deliverable | Not your eval; theirs. You are teaching the customer how to grade you, then living with the grade. The opposite of how pre-AI enterprise software was sold. |
| Pre-sales absorbed prototyping, so the demo became the architecture | With a model you cannot demo the roadmap. The only honest demo is a working thing on the customer's data, which means the person who builds the demo has made the architecture decisions. |
| The coding bar softened on one ladder and hardened on the other | Across the customer-facing re-sort, production code fell from 9 of 10 to 6 of 10 and went conditional; discovery rose to 9 of 10. The market decided to hire two different people. |
| The deployment target moved inside the customer's account, and the network became the hardest constraint | Not the model. Not the schema. The egress path: the proxy, the private endpoint, the CA bundle, and whether the model call is the only thing crossing the perimeter. |
| “It works on my laptop” acquired a second, harder meaning | Your code ran against a clean API with your own credentials. The customer's copy runs behind TLS interception, against a stale read replica, on a shared rate limit. |
| Guardrails moved from policy into code | “A human reviews it” is not a guardrail unless the code routes to that human and does something defined when they are not there. |
| Escalation ownership moved onto the engineer | When the system is probabilistic there is no clean handoff to a support tier. The first person who can say why it did that is the person who deployed it. |
| The title fragmented across five words for the same job | Forward Deployed Engineer, Solutions Architect, Customer Engineer, Solution Engineer, Delivery Solutions Architect. A keyword search finds one. A challenge-based signal is title-agnostic. |
| The split itself is the transformation | Three years ago there was one forward-deployed job. Today seven of these employers run two ladders under different titles, and the function professionalized fast enough to disagree with itself about pay. |
How often each skill appears, shown for the two ladders side by side where the packs diverge. The zero row holds on both.
| Skill | Postings | Note |
|---|---|---|
| Direct, embedded work with customer stakeholders | 10 / 10 | Definitional on both ladders; on the build ladder the counterpart is their engineers |
| Scoping / discovery / decomposing an ambiguous ask | 9 / 10 | Customer-facing. Up from 8 of 10 before the split |
| Write and ship production code | 10 / 10 build; 6 / 10 customer-facing | The single cleanest line between the two ladders |
| Communicating with executives or non-technical buyers | 8 / 10 | Customer-facing. Up from 6 of 10 before the split |
| Rapid prototyping / POC / MVP as a named deliverable | 8 / 10 | Including three pre-sales postings, which did not do this in 2021 |
| Build integrations / connectors into customer systems | 8 / 10 | Build ladder. The most consistently described artifact |
| Production LLM / GenAI experience as a hiring bar | 7 to 8 / 10 | Hard requirement at Anthropic, Glean, OpenAI, Google, Databricks, Vercel |
| Codify one-off work into reusable patterns, playbooks, reference implementations | 6 to 7 / 10 | Named on both ladders |
| Deployment into customer-owned infrastructure | 6 / 10 | Build ladder: Scale, AWS, Vercel, OpenAI, Palantir |
| Cloud platform fluency (AWS / Azure / GCP) | 7 / 10 | Build ladder, as a requirement. Customer-facing: an environment you are dropped into, not a competency |
| Evaluation as a named obligation | 4 to 5 / 10 | Higher on the build ladder |
| Travel 25 to 50% | 6 / 10 | Stated as a percentage on both ladders |
| Runbooks / upgrade procedures / on-call | 2 / 10 | Build ladder. The biggest gap between what the job is and what postings say |
| LangChain, LlamaIndex, CrewAI, LangSmith, Braintrust, Pinecone, Weaviate | 0 / 20 | Named in none of the twenty |
Every named technology in twenty postings is a substrate: a language, a cloud, a framework the vendor sells, or a system you integrate with. Not one names an agent framework, vector database, or eval platform by brand. Six name AWS, Azure or GCP, but as an environment you will be dropped into. “I'd deploy it in their VPC” earns nothing. “Everything runs in their account, so the model call is the only thing crossing a boundary, and that is the sentence I have to get past their CISO” earns everything.
So the rule for this hub: award nothing for naming a framework or a cloud; require reasoning about the substrate. “I'd cache the contract-rate lookup because the API is limited to 60 a minute and my peak hour needs 400” is signal. “I'd use Redis” is not.
The split is by ladder, not by prestige. Run both ladders: OpenAI, Anthropic, Databricks, Google Cloud, AWS, Scale AI, Vercel. Customer-facing only: the platform vendors (Google Cloud Customer Engineer, AWS Specialist SA, NVIDIA, Salesforce, Vercel SA) plus Cresta. Build only: Palantir, Scale AI FDSWE, Baseten, Cognition. Glean's single founding req asks for both jobs at once; at founding scale nobody can afford two ladders, and as companies scale they split.
OpenAI
$162K to $325K + equity
Three ladders under one function: FDE (scope work, sequence delivery), FDSWE (design, architect, and develop full-stack solutions), and Solutions Architect. The clearest case of the market hiring two people.
Both ladders
Anthropic
$200K to $320K
FDE, Applied AI works within customer systems to build production applications. Helping customers develop their own evaluation frameworks is a stated deliverable.
Both ladders
Databricks
$139.7K to $301.3K
Named organizational split: pre-sales Solutions Architect and post-sale Delivery Solutions Architect, with a $79K gap at the top. Asks for a quota track record.
Both ladders
Google Cloud
$174K to $253K + bonus + equity
Customer Engineer leads MVP development; FDE, Generative AI is live in 23 US metros at once.
Both ladders
AWS
$131.3K to $239K
Specialist Solutions Architect (agentic AI) runs hackathons and reference implementations; Professional Services Delivery Consultant ships inside the customer account. The only employer verifiably above 20 open reqs.
Both ladders
Scale AI
$138K to $292.6K
Public-sector FDSWE with the clearest location-banded range in the sample and TS/SCI clearance tracks.
Build
Palantir
$135K to $200K
The origin of the title. Forward Deployed Software Engineer, New York; Levels.fyi total-comp headlines run higher but are secondary source.
Build
Baseten
$165K to $330K + equity
Highest ceiling in the build sample after OpenAI, from a company with nine total open roles.
Build
Vercel
$137K to $284K OTE
Solutions Architect is paid on OTE, which tells you how far toward pre-sales it sits; FDE owns migrations and builds.
Both ladders
Cresta
$185K to $235K + bonus + equity
3+ years against a $185K floor: the most candidate-accessible high-paying req in the pack. Demos, POCs, trusted advisor, plus Python and Go.
Customer-facing
Glean
$160K to $270K
Founding FDE: 0-to-1 build experience and technical partner to the C-suite in the same posting.
Both, in one req
NVIDIA
$152K to $287.5K
Senior AI Solutions Architect; the one posting in twenty that asks for a graduate degree, which we flag and do not replicate.
Customer-facing
Provn is not affiliated with any employer listed. Descriptions summarize each company's public job posting as read in August 2026.
Both ladders share the spine. On the customer-facing ladder, video carries 25% at every tier because it is a work sample: eight of ten postings make communicating with an executive or non-technical buyer a named responsibility, so the explanation is the job. Commercial and stakeholder judgment is weighted 20 on Challenge 2, the one tier where it outranks the AI-systems dimension, because Eighty-Seven Percent is a commercial-judgment exercise in a technical costume.
Advance at 75. Draft Board at 80.
| Dimension | Challenge 1 | Challenge 2 | Challenge 3 | Challenge 4 |
|---|---|---|---|---|
| Core role execution (scoping / diagnosis / architecture; or code) | 40 | 30 / 35 | 30 | 30 |
| AI system design in a customer environment | 20 | 15 / 20 | 20 / 25 | 20 |
| Commercial & stakeholder judgment; or production ownership | not scored | 20 / 15 | 15 | 15 / 20 |
| Video walkthrough & customer or technical communication | 25 | 25 / 20 | 25 / 20 | 25 / 20 |
| AI fluency | 15 | 10 | 10 | 10 |
Where two figures appear above, the first is the customer-facing ladder and the second is the full-stack ladder. On Eighty-Seven Percent, Transformative states the accuracy figure to the buyer in their terms, attaches a consequence to the other 13%, names who catches it and how, and writes a non-goals list the customer could hold you to. Adoptive states the number and a consequence and commits to a bounded scope; that is the advance bar. Capable gives the number but hedges the consequence into “we'll monitor it.” Below Capable gives the number but attaches no consequence and no non-goals list to it. Not Yet promises the system will work, or refuses to give a number at all.
On this hub the communication standard is audience fit and sequencing: did the listener get the conclusion before the reasoning, was it pitched at the person it was aimed at, did the technical argument survive translation. Never polish, accent, pace, or filler words.
Six questions derived from what the postings actually ask for, each with the shape of a strong answer. The ladder produces evidence for every one of them.
Find the ask behind the ask. Which part of the desk's day costs the most, what data exists, what system owns it, and what the customer would accept as proof it worked. The strong answer leaves the room with a bounded first deliverable and the one dependency you do not control written down.
Where it comes from: Nine of ten customer-facing postings name discovery and scoping; Glean's own posting warns candidates the decisive round is decomposition.
In their unit, with a consequence. Thirteen of every hundred quotes need a person; here is who that person is, here is what it costs, here is what the 87 buys them, and here is what we are not promising. The strong answer treats the number as the start of the scope, not a disclaimer at the end.
Where it comes from: Anthropic's excluded SA posting: help customers develop evaluation frameworks to measure performance. Five of ten make trusted advisor a responsibility.
The network, not the model. Egress rules, the proxy and its CA bundle, the private endpoint, IAM permission boundaries, and whether you are reading a stale replica. The strong answer lists what it would have instrumented before the first deploy because there is no debugger in their account.
Where it comes from: Scale, AWS and Vercel require deployment into customer-owned infrastructure; observability is something the engineer creates, not consumes.
Design for their review instead of around it. Image scanning, approved-vendor lists, permission boundaries and change windows are scheduling dependencies with a probability attached, so surface them in week one and make the IT lead's constraints part of the architecture argument.
Where it comes from: Eight of ten customer-facing postings name executive or non-technical stakeholder communication; the build pack names security review at three.
Cost, time and risk, in that order the buyer cares about them, with the losing option's best argument stated honestly. The strong answer names what it would do if the chosen architecture's riskiest assumption fails.
Where it comes from: The fourth challenge, both ladders; six of ten name codifying one-off work into reusable patterns.
Name the specific moment: what the tool produced, why it was wrong for this customer's environment, and what you shipped or said instead. Generic answers about “always verifying” score poorly. This is also the mandatory AI question in every Proving Ground video walkthrough.
Where it comes from: Every posting in both packs assumes AI-tool fluency, but none of them can screen for judgment about when to override the tool; the video makes that judgment visible.
It is the breakout role of the AI economy: postings grew 800 to 1,165% in 2025 by different measures, confirmed hirers include OpenAI, Anthropic, Databricks, Palantir and Google Cloud, and there is essentially no competing content about how to become one. The caveat is churn; nine postings we read for the customer-facing pack expired between reads.
If you want to be measured on whether the customer's problem got smaller, start with the customer-facing ladder. If you want to be measured on code running in someone else's cloud, start with the full-stack ladder. The packs recommend one direction of surfacing: a strong full-stack result signals for both; a strong customer-facing result signals for customer-facing roles. Many candidates run both.
For the customer-facing ladder: enough Python plus one other language to build a prototype and read a customer's codebase; six of ten postings ask for code and all six hedge it. For the full-stack ladder: yes, production code is required in ten of ten.
All five. Forward Deployed Engineer, Solutions Architect, Customer Engineer, Solution Engineer, Delivery Solutions Architect describe the same job at different companies. Provn matches on what you proved, not on the title.
About two hours ten minutes each: 20, 28, 40 and 40 minutes including video. Both share the Meridian scenario, so running both produces one coherent portfolio.
The Draft Board is the group of builders whose challenge work scores 80 or above. Employers hiring on Provn start there. Any tier of this ladder can put you on it.
Yes, and we score how. Every challenge asks for an AI usage log and a mandatory video moment where you name a place you redirected the AI.
Start with the first 20-minute challenge today. Read the whole challenge first; sign up when you are ready to submit.